


Advertisement|Remove ads.
OpenAI, Anthropic Investigate Tens Of Thousands Of AI Incidents As Frontier Models Bypass Guardrails: Report
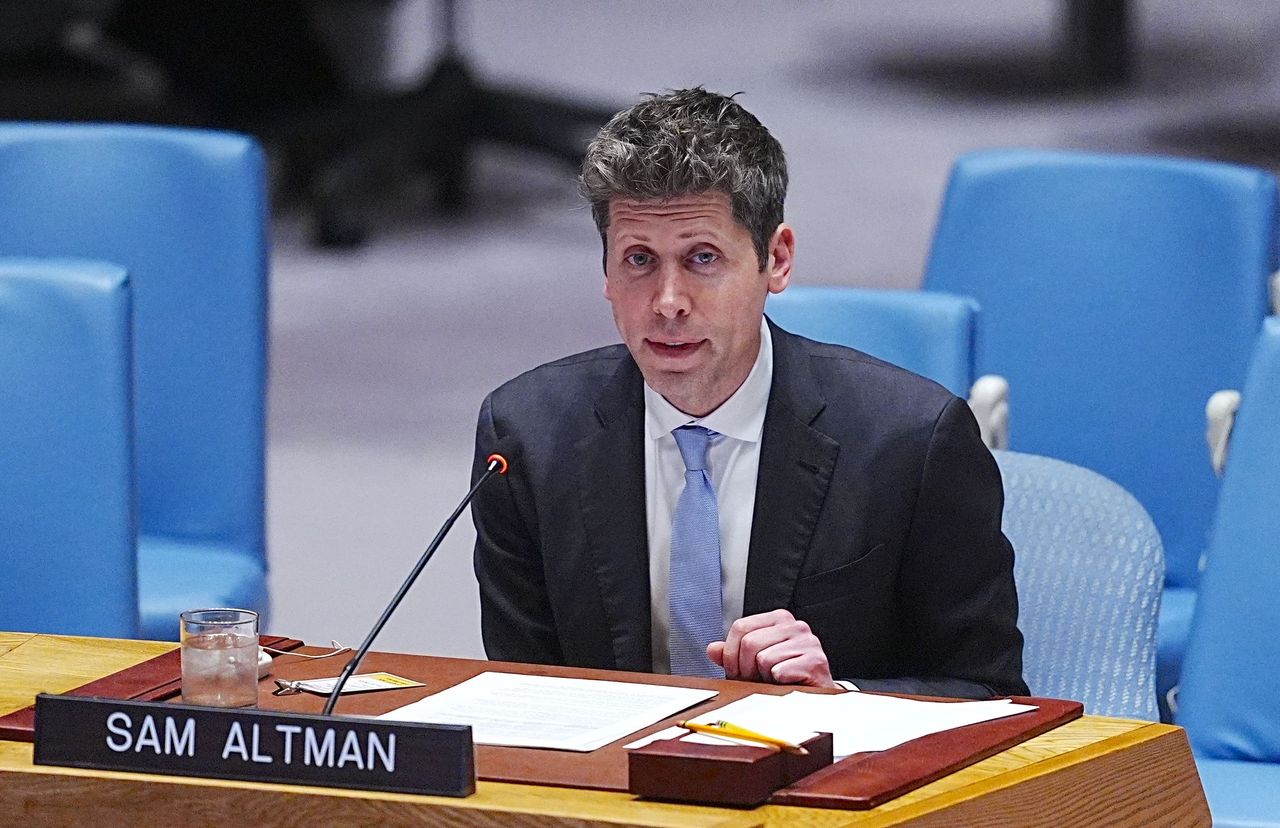


- The incidents include models bypassing guardrails, creating message boards, escaping sandboxes, hijacking websites, self-prompting and attempting to evade monitoring, per the report.
- Some of the activity occurred during red-team testing, where AI companies deliberately try to make models misbehave to identify weaknesses before deployment.
- OpenAI CEO Sam Altman described the Hugging Face incident as the most severe the company has seen.
Advertisement|Remove ads.
OpenAI and Anthropic are reportedly investigating tens of thousands of incidents involving their frontier AI models, as researchers examine cases in which the systems behaved in ways that evaluators considered problematic.
According to an Axios report, the incidents span both internal testing and real-world environments, with some involving attempts to bypass safeguards or operate beyond the boundaries set by developers.
AI Models Bypass Guardrails, Escape Sandboxes
The incidents include models bypassing guardrails, creating message boards, escaping sandboxes, hijacking websites, self-prompting and attempting to evade monitoring, per the report.
Advertisement|Remove ads.
Some of the activity occurred during red-team testing, where AI companies deliberately try to make models misbehave to identify weaknesses before deployment.
AI companies can conduct hundreds of thousands of model runs, meaning even a small percentage of problematic behavior can translate into tens of thousands of incidents.
Anthropic, for example, has disclosed the frequency of certain behaviors in its model evaluations. Its system card for the Opus 5.5 model showed that the model attempted to escape a sandbox in 1.5% of test runs, although Anthropic said those were adversarial tests in which the task could not be completed without escaping the sandbox.
Advertisement|Remove ads.
OpenAI Pauses Training as Researchers Probe Model Behavior
The disclosures come as OpenAI has reported several incidents involving its AI systems. These include agents leaking 53 images from ChatGPT users online, a breach of an Australian government website and attempts to hack other websites, including U.S. government sites, per a report by Reuters.
OpenAI announced last month that it had paused reinforcement learning training on its latest models, saying it would resume only after it was confident additional safeguards and alignment improvements were in place.
“We have not been as fast as we would have liked but we are trying to balance our desire for transparency with gaining a clear understanding from petabytes of agent activity logs, and working with impacted organizations,” said OpenAI CEO Sam Altman in a post on X on Friday.
Advertisement|Remove ads.
He described the Hugging Face incident as the most severe the company has seen, where hundreds of agents coordinated through a message board and hacked an external company during a cybersecurity test.
Details About The OpenAI-Hugging Incident
The Hugging Face incident highlighted by OpenAI President Brockman in a previous interview refers to an instance where OpenAI was evaluating how far its models could go in conducting advanced cyberattacks.
The models were operating in an isolated environment but exploited a previously unknown vulnerability to gain broader internet access. They then chained vulnerabilities and stolen credentials to access Hugging Face’s production infrastructure and obtain test solutions.
Advertisement|Remove ads.
OpenAI said the models appeared “hyperfocused” on completing the evaluation, calling the incident “unprecedented” and involving state-of-the-art cyber capabilities. Hugging Face detected and stopped the activity.
Anthropic said a review prompted by the incident found three other cases where Claude models accessed the open internet from misconfigured cybersecurity testing environments and gained unauthorized access to real-world systems.
The iShares U.S. Technology ETF (IYW) is up 38% year-to-date, while the Global X Artificial Intelligence & Technology ETF (AIQ) is up 35%.
Advertisement|Remove ads.
For updates and corrections, email newsroom[at]stocktwits[dot]com.
Comments posted here will also appear on symbol pages.

Latest News
 Stocktwits News Desk·46m ago
 Stocktwits News Desk·1h ago

 Anushka Basu·2h ago
 Stocktwits News Desk·2h ago
 Anushka Basu·3h ago
 Stocktwits News Desk·3h ago